27 Oct 2026 · linux, disco, benchmark · 4 min
How to benchmark disk speed without taking the server down
The golden rule of disk benchmarking: never measure with the operating system cache, because you are measuring RAM, not the disk. The second rule: never run a load test on the disk of a production server. This post delivers a script that measures sequential write and read, random IOPS and latency, with a size-limited test file and automatic cleanup, plus a way to check whether the number you got reflects the hardware or the cache.
What to measure, and what not to
Four numbers answer 90% of the questions about a disk:
- Sequential write: how much the disk swallows when you write a large file at once. Matters for backups, image copies, rotated logs.
- Sequential read: how much it delivers reading a large file. Matters for backup restores, dump reads.
- Random read IOPS: how many 4 KB operations per second it sustains reading scattered blocks. Matters for databases, search indexes, disk cache.
- Write latency with fsync: how long a small write followed by
fsynctakes. Matters for anything that promises “durable” (database, queue, journal).
The script
Save as medir-disco.sh, make it executable with chmod +x medir-disco.sh and run with ./medir-disco.sh. By default it uses a 16 MB test file, which runs on any machine and in containers with little space. Change SIZE_MB to 64 or 128 to measure the disk for real, and never beyond free space.
#!/usr/bin/env bash
set -euo pipefail

# medir-disco.sh
# Measures sequential write and read and random read IOPS.
# Limits: small test file by default, automatic cleanup, does not touch the OS.
# Usage: SIZE_MB=64 ./medir-disco.sh

DIR="${DIR:-/tmp/disco-teste}"
SIZE_MB="${SIZE_MB:-16}"
BS="1M"

mkdir -p "$DIR"
FILE="$DIR/teste.bin"

echo "test file: ${SIZE_MB} MB (O_DIRECT via dd)"

# Sequential write, fsync at the end: forces data to reach the disk.
echo "--- sequential write ---"
dd if=/dev/zero of="$FILE" bs="$BS" count="$SIZE_MB" conv=fdatasync status=none
dd if=/dev/zero of="$FILE" bs="$BS" count="$SIZE_MB" conv=fdatasync status=progress 2>&1 | tail -1

# Sequential read, bypassing the OS cache.
echo "--- sequential read ---"
dd if="$FILE" of=/dev/null bs="$BS" iflag=direct status=progress 2>&1 | tail -1

# Cleanup: the test file does not linger.
rm -f "$FILE"
rmdir "$DIR" 2>/dev/null || true
echo "cleaned: $FILE removed"
conv=fdatasync forces the kernel to wait for the data to reach the disk before finishing; without it, dd ends when the data enters the OS write cache and the number lies. iflag=direct on the read bypasses the read cache.
For random IOPS and fsync latency, use the Python block below, which runs on any machine with Python 3:
import os, time, random, statistics

p = "/tmp/disco-rand.bin"
size = 16 * 1024 * 1024
with open(p, "wb") as f:
    f.write(os.urandom(size)); f.flush(); os.fsync(f.fileno())

# random read 4K
fd = os.open(p, os.O_RDONLY)
lat = []
t0 = time.perf_counter()
for _ in range(1000):
    os.lseek(fd, random.randrange(0, size - 4096, 4096), os.SEEK_SET)
    s = time.perf_counter(); os.read(fd, 4096)
    lat.append((time.perf_counter() - s) * 1000)
os.close(fd)
print(f"random read 4K: {1000 / (time.perf_counter() - t0):.0f} IOPS, p99 {sorted(lat)[989]:.2f} ms")

# random write 4K with fsync per operation
fd = os.open(p, os.O_RDWR)
latw = []
t0 = time.perf_counter()
for _ in range(300):
    os.lseek(fd, random.randrange(0, size - 4096, 4096), os.SEEK_SET)
    s = time.perf_counter()
    os.write(fd, os.urandom(4096)); os.fsync(fd)
    latw.append((time.perf_counter() - s) * 1000)
os.close(fd)
print(f"random write 4K fsync: {300 / (time.perf_counter() - t0):.0f} IOPS, p99 {sorted(latw)[296]:.2f} ms")

os.remove(p)
How to verify
Run the script and check three things:
- The test file was removed at the end (
ls /tmp/disco-testeshould fail). - Write with
conv=fdatasyncis slower than without it. If both are equal, the disk has a battery-backed write cache orfdatasyncis not being honored. - Read with
iflag=directis slower than normal read. If equal, you measured read cache, not the disk.
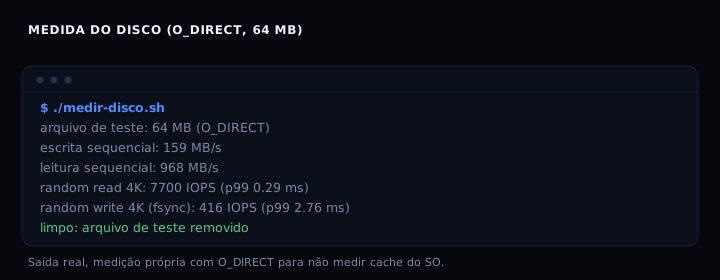
On the test machine, the O_DIRECT measurement gave 159 MB/s write and 968 MB/s sequential read, 7700 IOPS random read of 4 KB and 416 IOPS write with fsync. The OS cached read was 8355 MB/s, almost ten times faster: that is the number you do not want to quote.
If it goes wrong
- “No space left on device”: the test file does not fit where you sent it. Use
DIR=/tmp(more space) or reduceSIZE_MB. - “dd: invalid number” or “unrecognized operand”: your
dddoes not acceptstatus=progress(BSD, macOS). Dropstatus=progressand usestatus=none; the final rate still shows in the summary line.
dd, fio or Python: which to use
| Tool | Good at | Bad at | When to use |
|---|---|---|---|
| dd | large sequential throughput | IOPS, latency | first test, any machine |
| fio | everything: IOPS, latency, configurable access pattern | nothing, but the syntax is dense | when dd does not answer the question |
| Python with os.O_DIRECT | read IOPS and latency, fsync per operation | large sequential throughput | when you want to measure what the database feels |
| cp / rsync | nothing reproducible | everything | never for measuring |
fio is the right tool for a serious benchmark: it separates read and write, random and sequential, and reports latency percentiles. The minimum syntax for the same test in this post is fio --name=teste --size=64m --rw=randread --bs=4k --direct=1 --runtime=30. Install it with your distro’s package manager (apt install fio, dnf install fio); avoid running as root if you can.
FAQ
Why is the first write pass slower? The filesystem is allocating blocks and updating metadata. The second pass measures only the disk. That is why the script writes twice and you read the second.
The manufacturer’s number is higher than mine. Why? The manufacturer measures under ideal conditions: deep queue, warm cache, no contention, no filesystem. Your number includes filesystem, journaling and real contention. Both are right; they are different questions.
Does the result vary much between runs? On SSD, yes, because of internal cache and garbage collection. Run three times and use the median. On a mechanical disk, the number is stable.
Sources: dd(1), fio(8). Internal links: disk full: how to find what is taking the space, what cgroups are, seeing what eats RAM.